Explicit reference citation
Reasoning must name the reference box it uses. Correct coordinate citations earn reward; hallucinated coordinates are penalized.
“left of bbox=[205, 22, 511, 412]”Region-Grounded Multi-Round
Visual Reasoning
1 University of Amsterdam2 Anhui University3 Westlake University
Every turn of reasoning,
grounded in the image.
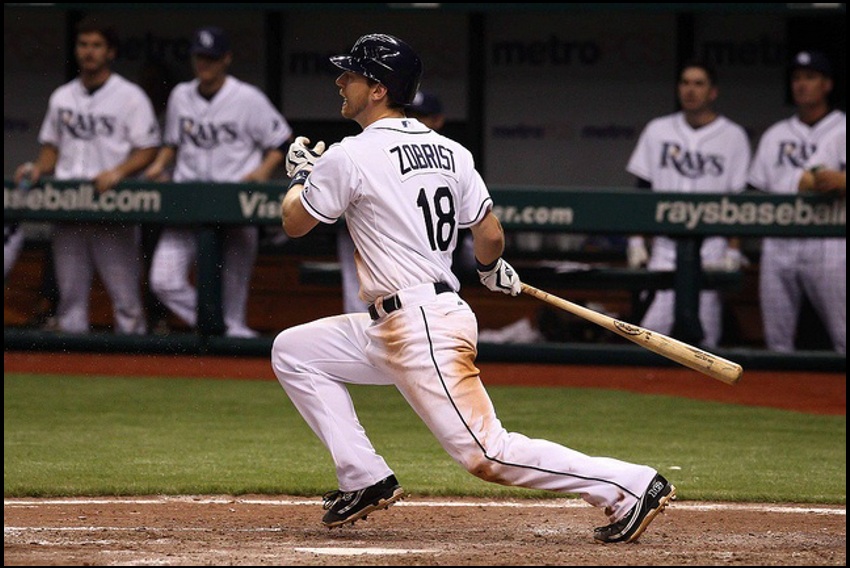
Find the player wearing jersey number 18.
<scene>Global contextA baseball game with a batter and several players in the dugout.
<focus>Local evidenceNo prior reference in this turn. Locate the player from the scene.
<think>Cite & relateThe foreground batter has 18 on his jersey. Ground the answer in that visible player.
<answer>Localize{"bbox_2d": [205, 22, 511, 412]}Adapted from the paper’s baseball example. Traces and output coordinates are simplified for explanation; this is an animation, not live inference.
In a visual dialogue, “the person next to that one” only makes sense if that one stays grounded.
RegionReasoner makes this connection explicit. Each turn carries forward localized regions, cites their bounding boxes in its reasoning, and keeps the reasoning aligned with both the whole image and the referenced region.
The result is a verifiable trajectory that supports referring detection and segmentation across multiple turns.
Large vision-language models have achieved remarkable progress in visual reasoning, yet most existing systems rely on single-step or text-only reasoning, limiting their ability to iteratively refine understanding across multiple visual contexts. To address this limitation, we introduce a new multi-round visual reasoning benchmark with training and test sets spanning both detection and segmentation tasks, enabling systematic evaluation under iterative reasoning scenarios.
We further propose RegionReasoner, a reinforcement learning framework that enforces grounded reasoning by requiring each reasoning trace to explicitly cite the corresponding reference bounding boxes, while maintaining semantic coherence via a global–local consistency reward. This reward extracts key objects and nouns from both global scene captions and region-level captions, aligning them with the reasoning trace to ensure consistency across reasoning steps.
RegionReasoner is optimized with structured rewards combining grounding fidelity and global–local semantic alignment. Experiments on detection and segmentation tasks show that RegionReasoner-7B, together with our newly introduced benchmark RegionDial-Bench, considerably improves multi-round reasoning accuracy, spatial grounding precision, and global–local consistency, establishing a strong baseline for this emerging research direction.
A 7B vision-language model, optimized with
structured rewards for multi-round grounding.
Reasoning must name the reference box it uses. Correct coordinate citations earn reward; hallucinated coordinates are penalized.
“left of bbox=[205, 22, 511, 412]”Keywords from the scene and reference-region captions are aligned with the reasoning. A spatial-language prior encourages explicit relations.
R(t) = Rbase(t) + Rref(t) + Rcons(t)
Optimize structured multi-turn rollouts with GRPO.Evaluating the chain,
one turn at a time.
A multi-round benchmark built from RefCOCO+ and RefCOCOg, spanning detection and segmentation.
Training propagates ground-truth references. At test time, later queries use the model’s previous predictions—so early errors can carry forward.
Explore the test data ↗Detection · RefCOCO+ Multi-turn
AP (%) ↑| Method | R1 | R2 | R3 | R4 | R5 | R6 | R7 | Avg* |
|---|
Source: Tables 1–2 of the paper. All models shown are 7B. *Aggregate values reproduce the paper’s reported “Avg”.
Later queries depend on earlier regions.
This qualitative example from the paper compares RegionReasoner and VisionReasoner over three turns. Explicit references help maintain the intended chain as the dialogue moves between people in a crowded scene.
Read, reproduce, and explore.
@inproceedings{sun2026regionreasoner,
title = {RegionReasoner: Region-Grounded Multi-Round Visual Reasoning},
author = {Wenfang Sun and Hao Chen and Yingjun Du and
Yefeng Zheng and Cees G. M. Snoek},
booktitle = {International Conference on Learning Representations},
year = {2026},
url = {https://arxiv.org/abs/2602.03733}
}